There are a couple I have in mind. Like many techies, I am a huge fan of RSS for content distribution and XMPP for federated communication.
The really niche one I like is S-expressions as a data format and configuration in place of json, yaml, toml, etc.
I am a big fan of Plaintext formats, although I wish markdown had a few more features like tables.
ISO 8601 date format. Not because it’s from a standards body, but because it’s simple, sensible, clearly defined, easy to recognize, and very effective.
Date field placement in any order other than most-significant-digits-first is not only counterintuitive, but needlessly complicated to work with. Omitting critical information like the century is ambiguous and confusing.
We don’t live in isolated villages any more. Mixing and matching those problems by accepting all the world’s various regional and personal date styles, especially with no reliable indication of which ones apply in any given case, leads to the hodgepodge of error-prone date madness that we have today.
The 2024-09-02 format should be taught in schools and required in official documents. Let the antiquated date styles fall into disuse outside of art and personal correspondence, like cursive writing.
RFC 3339 is a simplified profile of 8601 that only covers YYYY-MM-DD style formatting, if you only ever use that format and avoid the things like “2024-W36” they’re mostly interchangeable.
The week-of-year is far more relevant in Western Europe, and is used quite a bit in business. I have a Junghans watch that has a week complication.
It’s an important format outside of the US, and gives ISO-8601 an edge as a standard of conformance.
I had the fortune of being hired to build up from zero my department, and one of the first “rules” I made was all dates are ISO-8601 and now every process runs with 8601, if you use anything different your code is going to fail eventually when it finds another column date in 8601.
deleted by creator
That looks like an interesting diagram, but the text in it renders too small to read easily on the screen I’m using, and trying to open it leads to a javascript complaint and a redirect that activates before I can click to allow javascript. If it’s yours, you might want to look in to that.
The table below works, though. Thanks for the link.
deleted by creator
7 digit years feels way to optimistic, but I’ll be rooting for us.
I arrived to manage releases in a company, the previous manager named releases as “release04092016”, as USA standard. My first recommendation was to name releases as “releaseyyyymmdd” so “release20160409”. I was asked by another manager why to change that, so I showed her a sorted list of releases “git branches” and asked her, can you tell me there when was the last release? (a very common question) Of course, to find the last release you need to check the whole list because the mmddyyyy order is useless. The answer with yyyymmdd was immediate, just look at the last row.
Some countries already use it officially too :)
The year is the information that most of the time is the least significant in a date, in day to day use.
DDMMYY is perfect for daily usage.
Also, you can sort by ascending file names
It’s completely bonkers that JPEG-XL is as good as it is and no one wants to actually implement it into web browsers
What’s so good about it?
Basically smaller file sizes than JPEG at the same quality and it also automatically loads a lower quality version of the image before it loads a higher quality version instead of loading it pixel by pixel like an image would normally load. Google refuses to implement this tech into Chrome because they have their own avif format, which isn’t bad but significantly outclassed by JPEG-XL in nearly every conceivable metric. Mozilla also isn’t putting JPEG-XL into Firefox for whatever reason. If you want more detail, here’s an eight minute video about it.
I’m under the impression that there’s two reasons we don’t have it in chromium yet:
- Google initially ignored jpeg-xl but then everyone jumped on it and now they feel they have to create a post-hoc justification for not supporting it earlier which is tricky and now they have a sunk cost situation to keep ignoring it
- Google today was burnt by the webp vulnerability which happened because there was only one decoder library and now they’re waiting for more jpeg-xl libraries which have optimizations (which rules out reference implementations), good support (which rules out libraries by single authors), have proven battle-hardening (which will only happen over time) and are written safely to avoid another webp style vulnerability.
Google already wrote the wuffs language which is specifically designed to handle formats in a fast and safe way but it looks like it only has one dedicated maintainer which means it’s still stuck on a bus factor of 1.
Honestly, Google or Microsoft should just make a team to work on a jpg-xl library in wuffs while adobe should make a team to work on a jpg-xl library in rust/zig.
That way everyone will be happy, we will have two solid implementations, and they’ll both be made focussing on their own features/extensions first so we’ll all have a choice among libraries for different needs (e.g. browser lib focusing on fast decode, creative suite lib for optimised encode).
didn’t google include jpeg-xl support already in developer versions of chromium, just to remove it later?
Chromium had it behind a flag for a while, but if there were security or serious enough performance concerns then it would make sense to remove it and wait for the jpeg-xl encoder/decoder situation to change.
It baffles me that someone large enough hasn’t gone out of their way to make a decoder for chromium.
The video streaming services have done a lot of work to switch users to better formats to reduce their own costs.
If a CDN doesn’t add it to chromium within the next 3 years, I’ll be seriously questioning their judgement.
Chromium had it behind a flag for a while, but if there were security or serious enough performance concerns then it would make sense to remove it and wait for the jpeg-xl encoder/decoder situation to change.
Adobe announced they were supporting it (in Camera Raw), that’s when the Chrome team announced they were removing it (due to a “lack of industry interest”)
I think I would feel better using JPEG-XL where I currently use WebP. Here’s hoping for wider support.
Good news! I believe the Ladybird Browser intends to include support for JPEG XL.
JSON5. it’s basically just JSON with several QoL improvements, like comments, that make it usable as a format for human consumption (as opposed to a serialization format).
Objects may have a single trailing comma.
I just came.
I love that there’s someone out there who’s that passionate about JSON.
I hate grammers in anything that don’t support trailing commas. It’s even worse when it’s supported in some contexts and not others. Like lists are OK, but not function parameters.
TMI
TIL this exists
i’m a plan 9 from bell labs fan. Imagine how excited I was when wsl used 9P for its plumbing. then they scrapped it all for wsl2.
just, the power they managed to get out of those union mounts… your application wants access to the mouse? sure, here’s a file named “mouse”. it’s got the coordinates in it. you want to draw to the screen? here’s a file called like “bitmap” or whatever, just write to it. you want to start a process on another machine? just cd to it and start the process there. want to have the UI show up on your machine? symlink your bitmap file to that directory.
I also wish early web composability could have stayed and expanded. like, the old vlc embed player, which would just show up in your browser and could play any file inline? great stuff. Imagine if every application composed with everything else, like the android Activity and Intent concepts but for anything, just by virtue of living in the same os. need an image? just ask the os and it will present the user with many ways to procure an image, let the selected one run , and hand you back an image. you don’t even have to care where from. in a way, it’s what the arcan guy is doing with his experiments, although that’s more for stitching together graphical pipelines.
Plan 9 even extended the “everything is a file” philosophy to networking, unlike everybody else that used sockets instead.
Are sockets not files?
They’re “file like” in the sense that they’re exposed as an
fd, but they’re not exposed via the filesystem at all (Unlike e.g. unix sockets), and the existing API is just mapped over the sockets one (i.e.write()instead ofsend(),read()instead ofrecv()). There’s also a difference in how you create them, youopen()a file, butconnect()a socket, etc.(As an aside, it turns out Bash has its own virtual file-based wrapper around sockets, so you can do things like
cata remote port with Bash, something you can do natively in Plan 9)Really it just shows that “everything is a file” didn’t stand up in practice, there’s more stuff that needs special treatment than doesn’t (e.g. Interacting with TTYs also has special APIs). It makes more sense to have a better dedicated API than a generic catch-all one.
Depending where you use it, but often tables are available in markdown.
markdown table x y |markdown|table| |--|---| |x|y|Fixed…cos you could only see rendered and not code.
Oh. Good one. Markdown everywhere. Slack always pissed me off for it’s sub par markdown support.
There is an option in the settings to use markdown formatting. I haven’t tried it but I guess it at least makes formatting less annoying.
It’s a (small, shitty) subset of markdown. Slack formatting just kind of sucks.
I fixed it for you (markdown tables support padding to make them easy to read):
markdown table x y |markdown|table| |--------|-----| |x |y |deleted by creator, who realised their misunderstanding
Markdown tables are terrible though. Try and put a code block in there. Adoc tables are amazing on the other hand, but much more verbose to write.
I’d argue this syntax is difficult to read, especially as it scales
The syntax is only difficult to read in their example.
I fixed their example here: https://programming.dev/comment/12087783
I’ll give my usual contribution to RSS feed discourse, which is that, news flash! RSS feeds support video!
It drives me crazy when podcasters are like, “thanks for listening to our audio podcasts. We also have a video feed for our YouTube subscribers.” Just let me have the video in PocketCasts please!
I feel you but i dont think podcasters point to youtube for video feeds because of a supposed limitation of RSS. They do it because of the storage and bandwidth costs of hosting video.
I’d think they’d get it back by not having to share their ad rev with Google. There’s something to be said for the economies of scale Google benefits from but with cloud services that’s not as relevant as it was.
I just wrote a YouTube scraper and exported to RSS and into my podcast client. Using YouTube any other way is masochism in comparison.
Since nobody’s brought it up: MQTT.
It got pigeonholed into IoT world, but it’s a pretty decent event pubsub system. It has lots lf security/encryption options, plus a websocket layer, so you can use it anywhere from devices, to mobile, to web.
As of late last year, RabbitMQ started suporting it as a supported server add-on, so it’s easy to use it to create scalable, event-based systems, including for multiuser games.
I’m currently on the ZeroMQ boat. What made you go to Rabbit Mq? I need the Pair socket for zeroMq for a project.
Installed RabbitMQ for use in Python Celery (for task queue and crontab). Was pleasantly surprised it also offered MQTT support.
Was originally planning on using a third-party, commercial combo websocket/push notification service. But between RabbitMQ/MQTT with websockets and Firebase Cloud Messaging, I’m getting all of it: queuing, MQTT pubsub, and cross-platform push, all for free. 🎉
It all runs nicely in Docker and when time to deploy and scale, trust RabbitMQ more since it has solid cluster support.
MQTT is great! There are clients available in Python, JS, etc
Zigbee or really any Bluetooth alternative.
Bluetooth is a poorly engineered protocol. It jumps around the spectrum while transmitting, which makes it difficult and power intensive for bluetooth receivers to track.
I agree Bluetooth (at least Bluetooth Classic) is not very well designed, but not because of frequency hopping. That improves robustness and I don’t see why it would cost any more power. The hopping pattern is deterministic. Receivers know in advance which frequency to hop to.
I wish standards were always open access. Not behind a 600 dollar paywall.
When it is paywalled I’m irritated it’s even called a standard.
DP >> HDMI
I wish there was a good open standard for task management or todo list.
I know there’s todo.txt, but it lacks features like dependent tasks, and overall the plain text format limits features and implementations.
Do you know if it allows dependent tasks?
Yes, but not all clients expose dependent tasks (which is sadly a common issue with open standards: they aren’t always properly implemented). I’m using Tasks.org on my phone (which supports dependent tasks), synchronizing to a Nextcloud server with the Tasks app (which supports dependent tasks now,
but didn’t for a long time), which also syncs to Thunderbird (which does not appear to show dependent tasks as dependents).Edit: remembered that the Nextcloud Tasks app has long supported dependent tasks. I was thinking of recurring tasks, which it does not support. Again, open standards aren’t always fully implemented.
Well that’s still good news that I didn’t expect! I suppose I will look into that then. Thank you!
IRC.
Jabber.
IPFS.
I also pick this guy’s IRC
Yes and RSS feeds.
The term open-standard does not cut it. People should start using “publicly available and sharable” instead (maybe there is a better name for it).
ISO standards for example are technically “open”. But how relevant is that to a curious individual developer when anything you need to implement would require access to multiple “open” standards, each coming with a (monetary) price, with some extra shenanigans [archived] on top.
IETF standards however are actually truly open, as in publicly available and sharable.
why do we call standards open when they require people to pay for access to the documents? to me that does not sound open at all
Because non-open ones are not available, even for a price. Unless you buy something bigger than the “standard” itself of course, like a company that is responsible for it or having access to it.
There is also the process of standardization itself, with committees, working groups, public proposals, …etc involved.
Anyway, we can’t backtrack on calling ISO standards and their likes “open” on the global level, hence my suggestion to use more precise language (“publicly available and sharable”) when talking about truly open standards.
It’s a historical quirk of the industry. This stuff came around before Open Source Software and the OSI definition was ever a thing.
10BASE5 ethernet was an open standard from the IEEE. If you were implementing it, you were almost certainly an engineer at a hardware manufacturing company that made NICs or hubs or something. If it was $1,000 to purchase the standard, that’s OK, your company buys that as the cost of entering the market. This stuff was well out of reach of amateurs at the time, anyway.
It wasn’t like, say, DECnet, which began as a DEC project for use only in their own systems (but later did open up).
And then you have things like “The Open Group”, which controls X11 and the Unix trademark. They are not particularly open by today’s standards, but they were at the time.
(Holocene or) Human Era calendar
That would represent all human history as one.
And also, the Dekatrian calendar
Where we would have a less broken, more regular, year calendar that is almost align with the moon cycle.
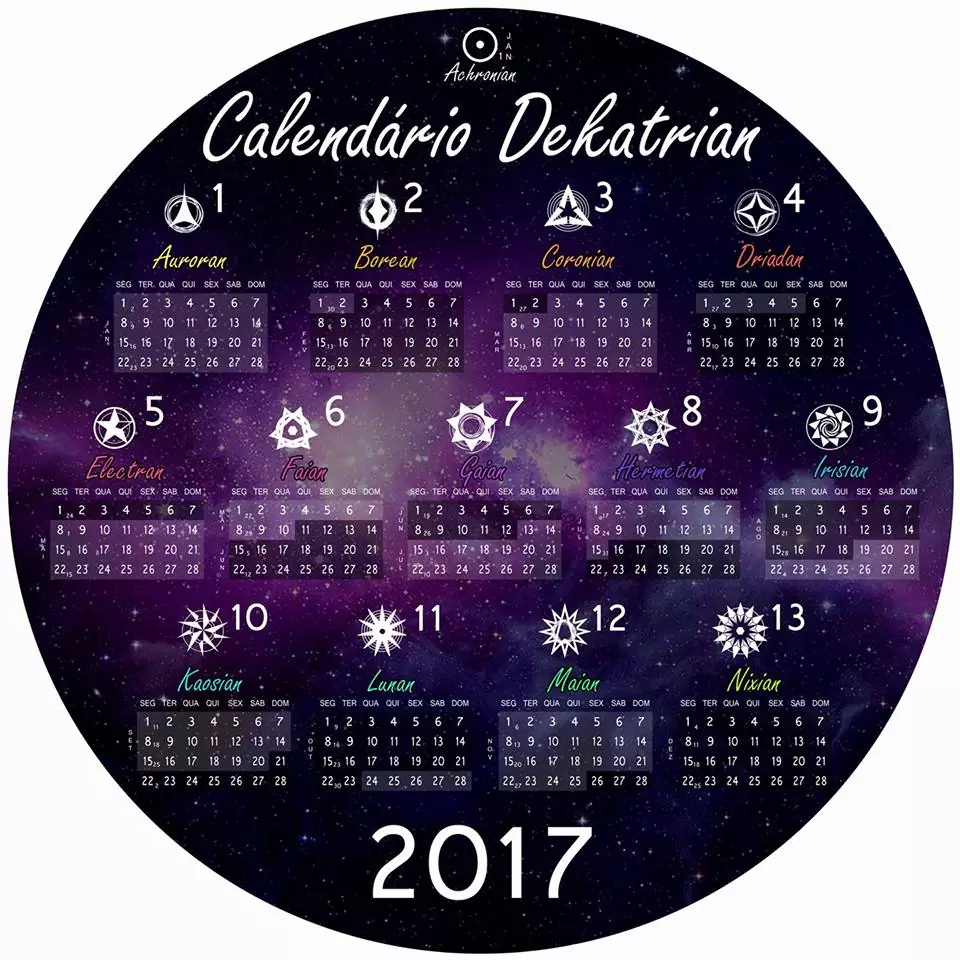
Oh many years ago in school I created something like that for an arts/creative writing project once, a calendar with 12, 30 day month based on sailor moon. Having it based on a magical girl manga gave me the freedom to declare the rest of the days to “days of evil” Was a fun project because I created a whole religion around it. 😁
That sounds interesting, would most likely not be very popular with lots of people and a pain in the butt to implement but interesting.
There’s a cool video from In a Nutshell about it some years ago.
GRPC for building APIs instead of REST. Type safety makes life easier
I mean, REST-ful JSON APIs can be perfectly type-safe, if their developers actually take care to make them that way. And the self-descriptive nature of JSON is arguably a benefit in really large public-facing APIs. But yeah, gRPC forces a certain amount of type-safety and version control, and gRPC with protobuf is SUCH a pleasure to work with.
Give it time, though, it’s definitely gaining traction.
It’s the recommended approach to replace WCF which was deprecated after .NET framework 4.8. My company is just now getting around to ripping out all their WCF stuff and putting in gRPC. REST interfaces were always a non-starter because of how “heavyweight” they were for our use case (data collection from industrial devices which are themselves data collectors).
The biggest problems with gRPC are:
- Very complicated. Way more complexity than you want in most cases.
- Depends on HTTP 2. I’ve seen people who weren’t even doing web stuff reach for gRPC, and now boom you have a web server in your stack for now reason. Compare to Thrift which properly separates out encodings, transports, etc.
- Doesn’t work from the web. There are actually two modifications to gRPC to make it work on the web which means you have three different incompatible versions of gRPC with different feature sets. IIRC some of them require setting up complex proxies, some don’t support streaming calls, ugh. Total mess.
Plain HTTP can be type safe. Just publish JSON schema or Typespec files or even use Protobuf.
Your concerns are all valid, but about 1 and 3 there are possible solutions. I’m using Rust+Tonic to build an API and that’s eliminate the necessity of proxies and it’s very simple to use.
I know that it don’t solve all problems, but IMHO is a question of adoption. Easier
toldtools will be develop for it.Depends on HTTP 2.
Doesn’t work from the web.
Am I the only one who is weirded out? Requiring a web server for something and then requiring another server if you want it to actually work on the web?
How expensive do people want to make their deployments?
TOML instead of YAML or JSON for configuration.
YAML is complex and has security concerns most people are not aware of.
JSON works, but the block quoting and indenting is a lot of noise for a simple category key value format.
deleted by creator
That’s “country-ist”. Nothing to do with the genes of people living over there.
deleted by creator
What in tarnation
TOML is not a very good format IMO. It’s fine for very simple config structures, but as soon as you have any level of nesting at all it becomes an unobvious mess. Worse than YAML even.
What is this even?
[[fruits]]
name = "apple"

[fruits.physical]
color = "red"
shape = "round"

[[fruits.varieties]]
name = "red delicious"

[[fruits.varieties]]
name = "granny smith"

[[fruits]]
name = "banana"

[[fruits.varieties]]
name = "plantain"
That’s an example from the docs, and I have literally no idea what structure it makes. Compare to the JSON which is far more obvious:
{
  "fruits": [
    {
      "name": "apple",
      "physical": {
        "color": "red",
        "shape": "round"
      },
      "varieties": [
        { "name": "red delicious" },
        { "name": "granny smith" }
      ]
    },
    {
      "name": "banana",
      "varieties": [
        { "name": "plantain" }
      ]
    }
  ]
}
The fact that they have to explain the structure by showing you the corresponding JSON says a lot.
JSON5 is much better IMO. Unfortunately it isn’t as popular and doesn’t have as much ecosystem support.
You’re using a purposely convoluted example from the spec. And I think it shows exactly how TOML is better than JSON for creating config files.
The TOML file is a lot easier to scan than the hopelessly messy json file. The mix of indentation and symbols used in JSON really does not do well in bigger configuration files.
JSON5
Nice. I mostly use Qt JSON and upon reading the spec, I see at least a few things I would want to have out of this, even when using it for machine-machine communication