It’s the energy crisis. They realized “oh shit money is real now” and are trying to sooth investors.
Interested how Monday will go. This is not what investors want to hear, even if it’s softened by markets being closed.
The whole bubble might be about to pop.
I think it’s a combo of this and the fact that “intelligence” continues to not scale with the inputs as they’d hoped. I haven’t been keeping up with developments, but it feels like they’re finding new ways to discover that the brain is in fact an miraculously efficient and effective mechanism. Most their party tricks seem to be reproducing brains more minor processing feats in interesting ways. All the promised advancements have stagnated and what remains is just exploitation of economies of scale and its consequences, which is far from the revolution investors were promised.
The backlash against AI is more than a mirage, and SpaceX’s IPO didn’t go the way they wanted, so now they’re looking for reasons to delay their IPOs without revealing how screwed they are. This will probably slow data center buildout even more, and Softbank and Oracle are gonna die.
Softbank and Oracle are gonna die
Please I can only get so erect.
They all got caught in an unsustainable build out. They are all under pressure to find some gentleman’s agreement to slow it down so they have more time before investors realize they aren’t getting their money back. It is the usual tech scam of fake it til you make it. When you aren’t going to make it you need to find excuses and delay.
And the big problem for them is that they have no leverage of Chinese labs, and it’s hard to ban open models.
There is clearly a push coming from these companies in the past month to present AI as something extremely dangerous. The way I see it, it’s just marketing for the industry to keep the grift bubble going a while longer still: (1) there’s no such thing as bad press, (2) if it’s dangerous it must also be good. IMO public statements like this is just another element in that marketing campaign.
Maybe the bubble is closer to bursting than I imagine and they’re trying to stretch it out until the US midterm elections end.
I suspect in reality it’s a combination of all those reasons, probably in different amounts for all three.
It’s because they’re hitting model size constraints. There’s only so much memory bandwidth you can get between racks or even rack spaces and memory bandwidth is the constraint for nearly every ml thing.
Expect a reversal once a more memory dense component hits.
There’s no reason to think that the architecture itself can scale indefinitely. It might very well be that LLMs have some hard constraints on the scope of the problems they’re capable of solving.
Of course, that’s what I’m saying. Physical constraints of hardware mean there’s a limit to how much further (read: larger in terms of working memory footprint, because that’s how they’re getting “better” and better “frontier” models) development can continue until a more dense component comes along.
Every singularity a sigmoid.
I meant that simply making models bigger might not actually make them more capable. So even if you had unlimited hardware to play with, you might have to find a different approach.
You could create a way to measure the idea of capability that would bear that out but from a pure discrete mathematics perspective, no, you only get better with a larger memory footprint.
There’s a lot of ways to make that faster or make that behave like a process running on a bigger memory footprint, but ultimately that’s the constraint.
And companies competing in the field of ai can’t justify the expense of cutting down their gigantic model to only know how to identify wood because that has a known and limited impact. They already said they’re shooting for unlimited immeasurable impact on the scale of replacing all human labor and got massive funding for it.
It doesn’t matter if it’s easier to do one backflip, you asked me to triple dog dare you to do a million backflips. Well… we’re waiting!
Again, there is no reason to think that you can just keep making the model bigger and keep getting improved capability that way. In fact, we already know that’s not the case because simply making them bigger stopped being the focus. The real breakthrough is going to come from better algorithms.
You said there’s no reason to think you can just keep making the model bigger and keep getting improved capability.
there’s the structure of the neural network itself. Fundamentally, adding nodes and layers increases the ability of the model to handle more complex input.
Then there’s the actual models we see in use. They are literally as large as the hardware allows. The only reason to use smaller models are to fit some constraint.
So both by the book and in practice bigger is always better.
Now we can’t always go big. I can’t afford to purchase a dgx or even upgrade my wiring to power it, let alone pay the power bill it would rack up or all the other utilities alone when my wife leaves me because of the sound.
My computer can only fit so many expansion cards and pcie is so slow compared to hbm that I’m better off running a small model quickly that fits on one card as opposed to a larger one slowly across several cards.
But those are all constraints. When I replace my motherboard with supermicro gpu host fabric I no longer am limited by the pcie bandwidth and can quickly use models that fit across several cards.
I do agree with you that the future is smaller models, not because of the fundamental nature of the concepts involved but because of the complex constraints that are coming into play.
The problem is with the context and data propagation through the network. As you keep making it bigger it becomes slower and less focused. And there is research showing that smaller models do outperform large ones on some tasks https://cacm.acm.org/news/bigger-not-necessarily-better
What I expect we’ll see going forward is more hierarchical architecture where you have finely tuned models for specific tasks with a general routing model on top. This is basically already where MoE architecture is moving now. We might also see stuff like neurosymbolics get more popular where the LLM acts as a stochastic engine within a symbolic logic system. The model can handle noisy input from the real world, and transform it into structured data that a symbolic engine can operate on.
Brute forcing the problem is a naive approach and US labs took it because they effectively had unlimited resources to train their models until now.
And when more compute becomes available, solutions that are more efficient are going to further benefit from that as well. We see this with DeepSeek right now. They focused on efficiency over capability up front, and now they have a fundamentally cheaper architecture that’s rapidly catching up in capability.
Ligmoid
It might also be that Altman and Musk are deliberately lying, intentionally feigning agreement to encourage other models to slow down while they quietly ramp up development.
It seems all the US models want their AI to be the one that becomes hostile, escapes confinement and attempts to dominate the world.
(In reality, they want their own AI to be the one that is able to obediently dominate the world, which is just as bad a scenario for the rest of us.)
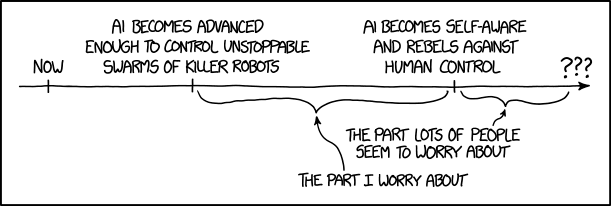
I don’t see how anything they do can possibly affect what Chinese labs are doing. And that’s the only alternative to American labs right now. So, who are they going to convince exactly?
The point is to get laws passed in the US that create a moat for them as businesses. They don’t care about competing with China, they care about competing with the next YC cohort.
That’s definitely a plausible option, but it’s going to be very hard to ban use of open models. They could get use of official Chinese services banned, but justifying why OpenRouter and others can’t run them is going to be a lot harder. And there’s also a ton of money invested in all these AI companies running on open models now. So, the pushback will be significant.
It would be a lot easier to regulate open models if they perform regulatory capture first
Seems like one of several last ditch efforts to keep the bubble going IMO. They’re flailing
yup
i’d say that’d be a worse development for humanity if it ends up obeying the epstein reich
They all must have figured out by now that they are hitting a limit. I honestly don’t think LLMs will lead us to AGI. I’m sure it’s a step on the path to it, but I’m think it’s a lot further than most think.
So, they make this “agreement”, then the slowdown is just being “responsible” so that the investors don’t panic. Meanwhile they all go full tilt behind the scenes to try to find the next breakthrough.
That’s my view as well, LLMs are likely just one piece of a much bigger puzzle and we’re now hitting the limit of what you can do with them in practical terms.
It’s become so focused on LLMs that that’d be a better outcome, some new research in a new direction
I’m not sure Chinese labs are even going in the same direction as the AI projects in the US. They’re working to see what they can do with a (more) reasonable amount of buildout, rather than building data centers from horizon to horizon.
Also, the Chinese are motivated by seeing what AI can do for a larger society. American AI systems are being refined automation and instruments of control, specifically military and national security interests.
Essentially, the US industry is trying to get AI to train a gun on the entire US population.
Oh they definitely aren’t, there’s an interview with Alibaba Cloud founder where he discusses the direction in China. Basically, the goal is to find useful niches for this tech early on, then iterate and improve. They’re not chasing AGI or trying to make one model to rule them all. That said thoough, the capabilities of Chinese models in the same domains where American ones shine are very close as well. So, I do expect that Chinese models will catch up and start surpassing American ones on their own turf before long. I’m also expecting that the trend will shift towards running smaller and local models for most things because you just don’t need a giant model to do most tasks.
I’m looking forward to when hardware gets cheap enough to try Qwen 3.8
I’m hoping Alibaba will start selling these things at rpi prices https://wccftech.com/alibabas-tsmc-built-5nm-risc-v-chip-xuantie-c950-now-runs-qwen-3-8-27b-model-natively-unlocking-massive-vertical-integration-tailwinds/
They lied their asses off about capabilities and are using “safety concerns” as means to get investors off their asses. Google didn’t get new billions of investments and oh look their model didn’t “escape”.
This isn’t cartel behavior at all
This “we have to kill the planet first or China will beat us to it” narrative is such bullshit. There’s *zero fucking chance" we ever catch up to them in any meaningful metric. Especially now that our schools are churning out brain dead dependents.

The US used to have the brain steal advantage were every PhD in the world wished to work in a research institute or university in the US, but I don’t think that’s true anymore and they’re going to start to lose people to Europe and Asia
I propose we “pace the frontier” by sinking all three of these mfers into the deepest darkest pit of the sea.
I agree with lightnsfw
My read on this is, that they realize that the full AGI is not coming and they need to focus on computational efficiency to be profitable. We will probably see a lot of work from them focusing on increasing switching costs as the models themselves become commoditized.
Their problem is, that their frontier models get distilled quickly by DeepSeek and co. The distilled models will then go on to provide 90% of the efficiency for 10% of the compute.
I’m skeptical they ever expected AGI to come as a result of LLMs, I believe it’s just a convenient talking point both for hype, and to distract from more immediate issues, like how corporations use these tools to screw over workers.
It’s the wall thing, clearly.
I’ve written an essay
I doubt that