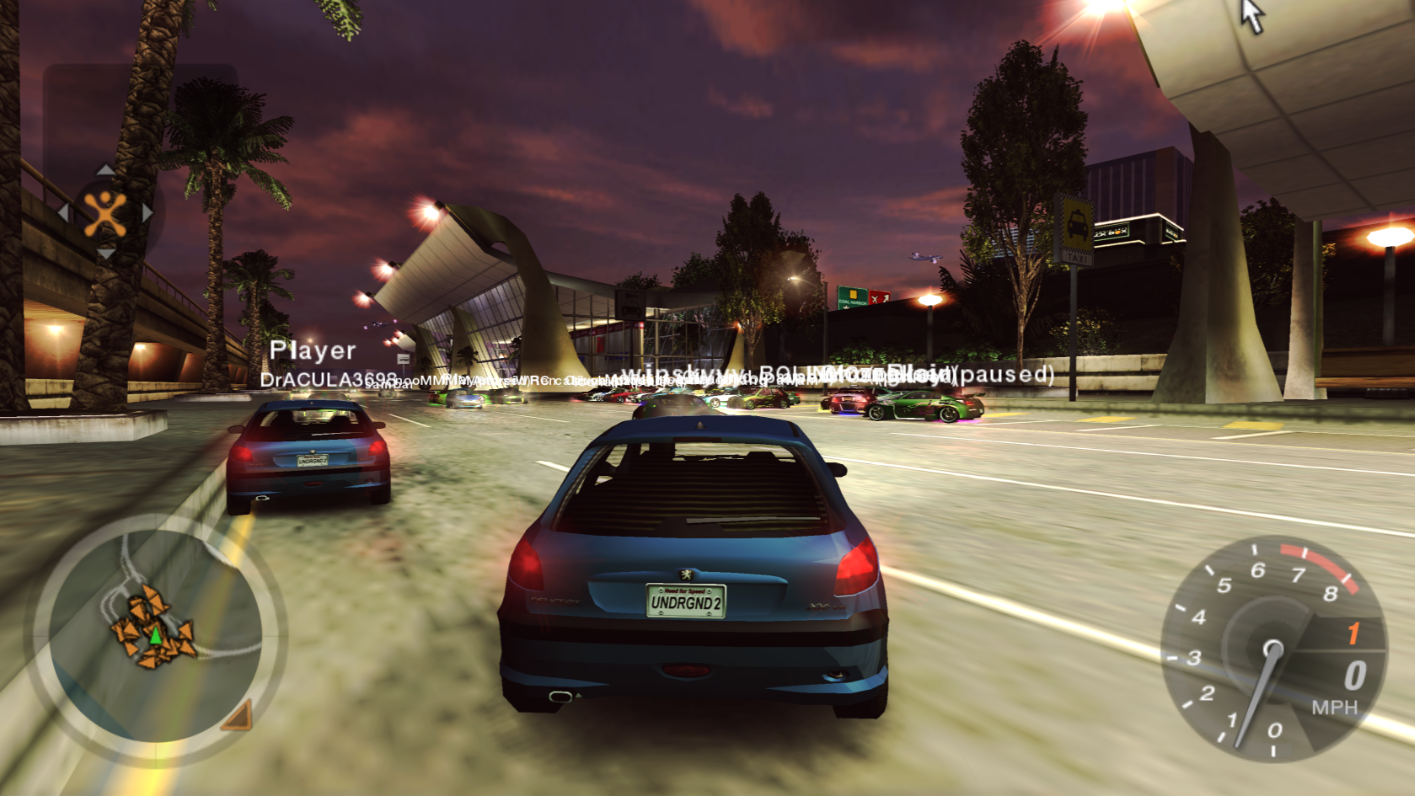
It was always possible. It was always the billionaires needing more money more than they needed their slave studios to make good entertainment

Hot Pursuit was better
No way. No shade to Hot Pursuit (also a banger), but this game was right place, right time. Probably the best timed game in history. NFSU1 has a special place in my heart too, but this one was next level.
I’ve been a part of the modding scene for these games for about a decade now.
As easy as this is to get running, which is a great thing, I feel the effort to make this has been misplaced and that this is a fad which will die off in a month’s time.
There are many better ways to go about this and, more importantly, there are much bigger issues to solve (such as lack of any meaningful new content for these games). It’s historically always been limited due to the lack of tooling that is functional and user-friendly enough to craft mods for this game.
And that is changing for the better, for sure. But all of these slopped up mods and ports are just made for clout to ask for donos. It doesn’t feel right because there’s almost always no passion (or even any effort) put into this.
It’s alright. It’s no Burnout 3 though.
Glorious.
- Slop
- No link to the web site
Why do “news” sites always forget to put links to external resources?
Because you might click the link and leave the news site.
Source: worked in the industry, literally told this.
Publisher relations is another reason. I don’t think EA appreciates this.
Been there too. I think it was Warner Brothers (at the time) that had a hissy fit about a review of a game. They didn’t like the review: they wanted advertising rather than editorial. We told them to talk to the sales department.
Do you remember which game it was?
A very early Harry Potter game, 2001. Surprise, it was EA.
Yeah whenever I link to a science article I always include a link to the paper that it is written about if it is open access in my lemmy posts and yet in the damn popscience articles I am linking to from reputable websites they hide the links to the actual research as if to condescend you or send the message it isn’t for you… even when the research is OPEN ACCESS.
Why is it hidden in a blue link in the body of the article amid 40 other tangentially relevant blue links? …or why is the link put as a fineprint at the bottom of the article rather than being emphasized as the thing the article is talking about???
It is pathetic and it pisses me off. It is one of the reasons I am so motivated to link directly to open access research when covering it in a general news context.
longer bit on my perspective about public science advocacy
I don’t know who someone reading my post is, they could be a dog, a PHD, a bot, a farmer… who knows why should I assume they wouldn’t be interested in taking a glance at the actual paper? Do you even know yourself well enough to know you aren’t the kind of person that might be interested in the actual science until we design media so that the link to papers is displayed clearly and naturally, not to pressure anyone into it but rather as a trap to lure in and grab onto curious minds and send them on a journey?!
I genuinely think this changes how people perceive science in general when they can peak in, flip through a couple of current scientific papers, ask a couple of questions and be like “cool, I never thought about that!” and then move on. The status quo of Elsevier slapping you with a $45 price tag to read an article you might find useless or indecipherable is just insulting and in my opinion pushes the general public towards feeling fundamentally seperated from science. I also find it insufferable when scientists and writers claim the average person isn’t going to read a complex scientific paper to which again I reiterate I don’t like to assume I know who the people will be that read my posts/links, I have no idea! Maybe they don’t know either, so why not? Don’t we all win just a tiny bit if someone checks out a scientific paper just briefly out of mild curiousity? I think we do…
Agreed on the slop part. There’s a Twitter post embedded with a link to the site in the article.
Instead of playing this AI slop that has to play on chrome, according to one comment, why not help GOG get it. It’s currently near the top for most votes on the GOG wishlist.
Because playing nfsu2 is fun.
Not gonna happen. Car, music and other licensing makes this practically impossible. These licenses are only for a limited number of years - renewing them is often ridiculously expensive, to the point of usually making no economic sense. It’s the main reason why old racing games like this one are not available digitally.
Even Rockstar was forced to re-release their older GTAs with some music tracks removed (and they had to patch it for existing owners as well). If it’s too expensive for them and far higher profile titles, you know it’s not going to happen for a game like Underground 2.
Playing on Firefox with no issues. I’d love a natively running program, though.
You can get it from archive.org. There even is a lutris install script which downloads and patches it:
I have my old PS2 and the disc still sitting around :D
My biggest regret is selling my old game consoles because it was becoming a burden to store them in our old place. Our new place is much bigger and I could easily have them all in my office.
You can easily emulate them all these days. I know it’s not the same, but often times, that’s actually a good thing. It’s far less of a hassle to play older titles on modern devices than to hook up an analog output era console to a modern TV and getting a good image quality out of the combination. Not to mention, performance and resolution were often much worse than you remember. Hell, some emulators even fix bugs and you can easily play ROM hacks or other mods that way - which sometimes also fix bugs, like a fan-patched version of Gran Turismo 2, which makes it actually possible to complete the game.
True. I was going to start getting into Pokemon Rom hacks.
https://github.com/th0mk/nfsu2-web
Last updated 5 minutes ago.
This is SOOOO SICK. I’ve never played any NFS games, and this is a blast so far. Thank you for this!
I grew up on NFS:U2
it’s a great game. speed done right, car controls done right. atmosphere done right. progression done well.
it’s a good game.
I played through this entire game several times using an SNES controller that my brother rigged up to an old printer cable. It worked perfectly.
That’s certainly a unique sentence no other person has ever uttered before.
Wrong. Shoehorning controllers (and some other protocols like Nokia phone flashing) to serial and parallel ports has been around since when the ports were invented.
Example: https://www.raphnet.net/electronique/psx_adaptor/psx_adaptor_en.php
It enjoys crashing almost as much as I do in Burnout 3.
Can this slop garbage stop getting headlines? Fucking Christ.
I do find it fascinating that people are actually able to get AI to do anything useful. I assume they’re using something fed more specific training data? Anytime my work told us to use AI for anything it fucking sucked. Caused more work/ time than actually figuring out how to code something yourself
I assume they’re using something fed more specific training data?
Not at all, any frontier model can do it. Most people use Claude Opus 5.5 to make these things. I’m assuming you were using a worse one at your work, because the newest ones are pretty impressive.
It’s possible(probable) that I just don’t understand how to use AI in an effective way to actually have it do what I want. At work we used chatgpt along with cursor. I mainly used cursor but it could also have been that we were using proprietary systems. It did however seem it would give me weird answers even when I gave it source code to work with.
Things have come along quickly and are speeding up rather than slowing down.
At least people aren’t parroting that tired old, ‘This exact thing must already exist in the training data’ argument which has been fallacious from the start but is wearing excessively thin since new models use almost exclusively synthetic training data to begin with.
From experience listening to a coworker who has used AI a lot. You really need to tell it everything it has to do, slowly. It will try repeatedly to do something you didn’t ask it to, and you will need to tell it repeatedly to undo it, and to not make up solutions to problems that aren’t there.
I think a lot of people make the mistake of telling it something like “I need to make a program that can do z, x and y”. The ai will then fill in whatever gaps you didn’t mention between z, x and y, without asking, just guessing.
I only have very limited experience, but from what I’ve personally figured out, another good practice is to look into the thinking process (even though models can and do “lie” in there, so it’s not really the actual thing that’s happening under the hood) and catch mistakes early before the AI has wasted a bunch of time and (possibly) money on some nonsensical detour. You then have to stop the process early, add a line or two to the prompt to explicitly stop it from choosing this detour and start again. (In my case - I almost exclusively use local LLMs - it’s not about money, at least not directly, but because there’s only a very limited context memory due to the amount of RAM I have, so I don’t want it to be filled up by stuff that’s not helpful.)
It’s like babysitting a toddler. The moment you look away, chances are it might try something you really don’t want to happen.
Sometimes, the LLM might misunderstand your prompt entirely, because you chose imprecise language, made a typo that changes the meaning, you asked something of it that is way outside of its ballpark/training data, because of missing context or because the AI just had another dumb moment.
The old adage that computers are just as smart or dumb as the user (but much faster at it) often applies to AI as well, at least in certain use cases - in others, AI can actually help less intelligent users, but at the same time drag down smart people and erode their skills over time. It’s weird what it’s doing to our brains, which is why I’m very wary of using it for anything other than experimentation and fun, and avoid using it for things that are actually important to me. Many people don’t have this choice though, with mandatory AI usage in many orgs still being on the rise.