
Non paywalled link https://archive.is/VcoE1
It basically boils down to making the browser do some cpu heavy calculations before allowing access. This is no problem for a single user, but for a bot farm this would increase the amount of compute power they need 100x or more.
Exactly. It’s called proof-of-work and was originally invented to reduce spam emails but was later used by Bitcoin to control its growth speed
It’s funby that older captchas could be viewed as proof of work algorithms now because image recognition is so good. (From using captchas.)
Interesting stance. I have bought many tens of thousand of captcha soves for legitimate reasons, and I have now completely lost faith in them
That’s actually a good idea. A very simple “click the frog” captcha might be solvable by an AI but it would work as a way to make it more expensive for crawlers without wasting compute resources (energy!) on the user or slowing down old devices to a crawl. So in some ways it could be a better alternative to Anubis.
it wasn’t made for bitcoin originally? didn’t know that!
Originally called hashcash: http://hashcash.org/
you know it’s old when it doesn’t have ssl
TIL
It inherently blocks a lot of the simpler bots by requiring JavaScript as well.
Thank you for the link. Good read
My archive’s server uses Anubis and after initial configuration it’s been pain-free. Also, I’m no longer getting multiple automated emails a day about how the server’s timing out. It’s great.
We went from about 3000 unique “pinky swear I’m not a bot” visitors per (iirc) half a day to 20 such visitors. Twenty is much more in-line with expectations.
I’ve seen this pop up on websites a lot lately. Usually it takes a few seconds to load the website but there have been occasions where it seemed to hang as it was stuck on that screen for minutes and I ended up closing my browser tab because the website just wouldn’t load.
Is this a (known) issue or is it intended to be like this?
anubis is basically a bitcoin miner, with the difficulty turned way down (and obviously not resulting in any coins), so it’s inherently random. if it takes minutes it does seem like something is wrong though. maybe a network error?
adding to this, some sites set the difficulty way higher then others, nerdvpn’s invidious and redlib instances take about 5 seconds and some ~20k hashes, while privacyredirect’s inatances are almost instant with less then 50 hashes each time
So they make the internet worse for poor people? I could get through 20k in a second, but someone with just an old laptop would take a few minutes, no?
So they make the internet worse for poor people? I could get through 20k in a second, but someone with just an old laptop would take a few minutes, no?
i mean, kinda? you are absolutely right that someone with an old pc might need to wait a few extra seconds, but the speed is ultimately throttled by the browser
Well, it’s the scrapers that are causing the problem.
Isn’t that just the way things work in general though? If you have a worse computer, everything is going to be slower, broadly speaking.
Just wait till they hit my homepage with a 200mb react frontend, 9 seperate tracking / analytics scripts and generic shopify scripts on it :P
I have had a similar experience. Most sites with Anubis take only a few seconds to go through, but I ran into I think it was some small blog where it took at least 5 minutes. Like someone mentioned, it may have been how they set it up with number of hashes required. The site that took forever for me seemed to have some exorbitant number like 5k or 50k (I don’t recall exactly).
<Stupidquestion>
What advantage does this software provide over simply banning bots via robots.txt?
</Stupidquestion>
Robots.txt expects that the client is respecting the rules, for instance, marking that they are a scraper.
AI scrapers don’t respect this trust, and thus robots.txt is meaningless.
Well, now that y’all put it that way, I think it was pretty naive from me to think that these companies, whose business model is basically theft, would honour a lousy robots.txt file…
the scrapers ignore robots.txt. It doesn’t really ban them - it just asks them not to access things, but they are programmed by assholes.
TL;DR: You should have both due to the explicit breaking of the robots.txt contract by AI companies.
AI generally doesn’t obey robots.txt. That file is just notifying scrapers what they shouldn’t scrape, but relies on good faith of the scrapers. Many AI companies have explicitly chosen not no to comply with robots.txt, thus breaking the contract, so this is a system that causes those scrapers that are not willing to comply to get stuck in a black hole of junk and waste their time. This is a countermeasure, but not a solution. It’s just way less complex than other options that just block these connections, but then make you get pounded with retries. This way the scraper bot gets stuck for a while and doesn’t waste as many of your resources blocking them over and over again.
The difference is:
- robots.txt is a promise without a door
- Anubis is a physical closed door, that opens up after some time
The problem is Ai doesn’t follow robots.txt,so Cloudflare are Anubis developed a solution.
Just recently there was a guy on the NANOG List ranting about Anubis being the wrong approach and people should just cache properly then their servers would handle thousands of users and the bots wouldn’t matter. Anyone who puts git online has no-one to blame but themselves, e-commerce should just be made cacheable etc. Seemed a bit idealistic, a bit detached from the current reality.
Someone making an argument like that clearly does not understand the situation. Just 4 years ago, a robots.txt was enough to keep most bots away, and hosting personal git on the web required very little resources. With AI companies actively profiting off stealing everything, a robots.txt doesn’t mean anything. Now, even a relatively small git web host takes an insane amount of resources. I’d know - I host a Forgejo instance. Caching doesn’t matter, because diffs berween two random commits are likely unique. Ratelimiting doesn’t matter, they will use different IP (ranges) and user agents. It would also heavily impact actual users “because the site is busy”.
A proof-of-work solution like Anubis is the best we have currently. The least possible impact to end users, while keeping most (if not all) AI scrapers off the site.
This would not be a problem if one bot scraped once, and the result was then mirrored to all on Big Tech’s dime (cloudflare, tailscale) but since they are all competing now, they think their edge is going to be their own more better scraper setup and they won’t share.
Maybe there should just be a web to torrent bridge sovtge data is pushed out once by the server and tge swarm does the heavy lifting as a cache.
No, it’d still be a problem; every diff between commits is expensive to render to web, even if “only one company” is scraping it, “only one time”. Many of these applications are designed for humans, not scrapers.
If the rendering data for scraper was really the problem Then the solution is simple, just have downloadable dumps of the publicly available information That would be extremely efficient and cost fractions of pennies in monthly bandwidth Plus the data would be far more usable for whatever they are using it for.
The problem is trying to have freely available data, but for the host to maintain the ability to leverage this data later.
I don’t think we can have both of these.
I don’t understand how/why this got so popular out of nowhere… the same solution has already existed for years in the form of haproxy-protection and a couple others… but nobody seems to care about those.
Probably because the creator had a blog post that got shared around at a point in time where this exact problem was resonating with users.
It’s not always about being first but about marketing.
It’s not always about being first but about marketing.
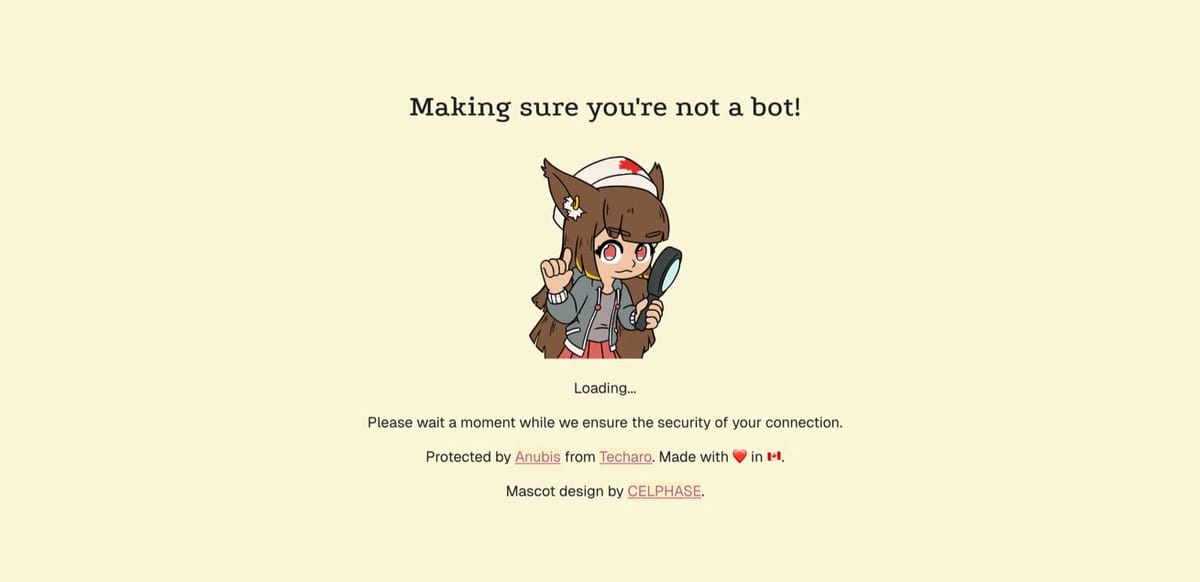
And one has a cute catgirl mascot, the other a website that looks like a blockchain techbro startup.
I’m even willing to bet the amount of people that set up Anubis just to get the cute splash screen isn’t insignificant.Compare and contrast.
High-performance traffic management and next-gen security with multi-cloud management and observability. Built for the enterprise — open source at heart.
Sounds like some over priced, vacuous, do-everything solution. Looks and sounds like every other tech website. Looks like it is meant to appeal to the people who still say “cyber”. Looks and sounds like fauxpen source.
Weigh the soul of incoming HTTP requests to protect your website!
Cute. Adorable. Baby girl. Protect my website. Looks fun. Has one clear goal.
I get that website admins are desperate for a solution, but Anubis is fundamentally flawed.
It is hostile to the user, because it is very slow on older hardware andere forces you to use javascript.
It is bad for the environment, because it wastes energy on useless computations similar to mining crypto. If more websites start using this, that really adds up.
But most importantly, it won’t work in the end. These scraping tech companies have much deeper pockets and can use specialized hardware that is much more efficient at solving these challenges than a normal web browser.
she’s working on a non cryptographic challenge so it taxes users’ CPUs less, and also thinking about a version that doesn’t require JavaScript
Sounds like the developer of Anubis is aware and working on these shortcomings.
Still, IMO these are minor short term issues compared to the scope of the AI problem it’s addressing.
To be clear, I am not minimizing the problems of scrapers. I am merely pointing out that this strategy of proof-of-work has nasty side effects and we need something better.
These issues are not short term. PoW means you are entering into an arms race against an adversary with bottomless pockets that inherently requires a ton of useless computations in the browser.
When it comes to moving towards something based on heuristics, which is what the developer was talking about there, that is much better. But that is basically what many others are already doing (like the “I am not a robot” checkmark) and fundamentally different from the PoW that I argue against.
Go do heuristics, not PoW.
I don’t like it either because my prefered way to use the web is either through the terminal or a very stripped down browser. I HATE tracking and JS
It takes like half a second on my Fairphone 3, and the CPU in this thing is absolute dogshit. I also doubt that the power consumption is particularly significant compared to the overhead of parsing, executing and JIT-compiling the 14MiB of JavaScript frameworks on the actual website.
It depends on the website’s setting. I have the same phone and there was one website where it took more than 20 seconds.
The power consumption is significant, because it needs to be. That is the entire point of this design. If it doesn’t take significant a significant number of CPU cycles, scrapers will just power through them. This may not be significant for an individual user, but it does add up when this reaches widespread adoption and everyone’s devices have to solve those challenges.
A javascriptless check was released recently I just read about it. Uses some refresh HTML tag and a delay. Its not default though since its new.
The source I assume: challenges/metarefresh.
I agree. When I run into a page that demands I turn on Javascript for whatever purpose, I usually just leave. I wish there was some way to just not even see links to sites that require this.
Open source is also the AI scraper bots AND the internet itself, it is every character in the story.
I had seen that prompt, but never searched about it. I found it a little annoying, mostly because I didn’t know what it was for, but now I won’t mind. I hope more solutions are developed :D
deleted by creator