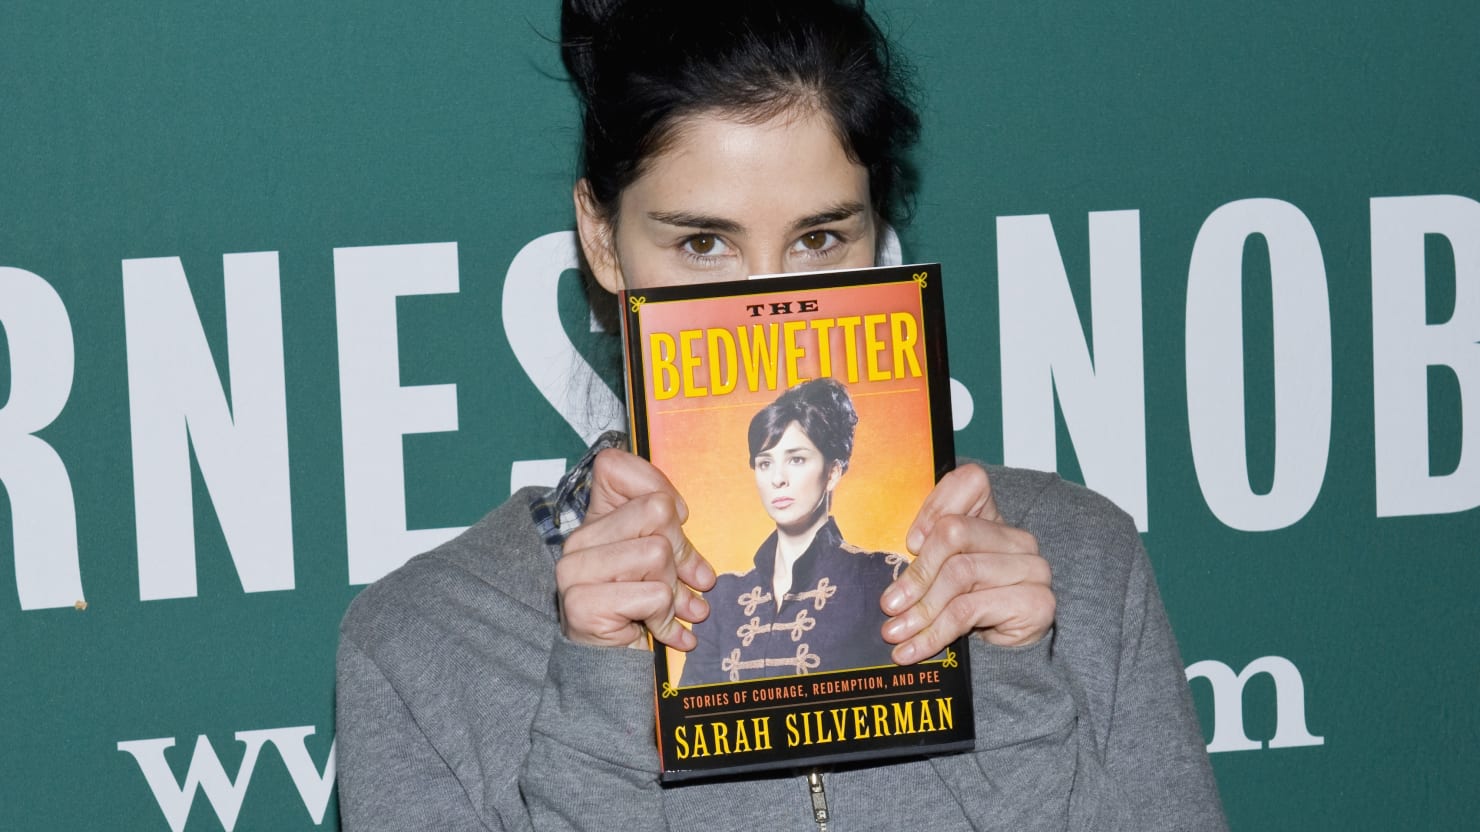
Arthur Besse ( cypherpunks@lemmy.ml ) to TechnologyEnglish · 3 years agoSarah Silverman and other authors are suing OpenAI and Meta for copyright infringement, alleging that they're training their LLMs on books via Library Genesis and Z-Librarywww.thedailybeast.comexternal-linkmessage-square123linkfedilinkarrow-up1220cross-posted to: piracy@lemmy.mlchatgpt@lemdro.id
arrow-up1220external-linkSarah Silverman and other authors are suing OpenAI and Meta for copyright infringement, alleging that they're training their LLMs on books via Library Genesis and Z-Librarywww.thedailybeast.comArthur Besse ( cypherpunks@lemmy.ml ) to TechnologyEnglish · 3 years agomessage-square123linkfedilinkcross-posted to: piracy@lemmy.mlchatgpt@lemdro.id
minus-squareag_roberston_author ( ag_roberston_author@beehaw.org ) linkfedilinkEnglisharrow-up63·3 years agoThis is a strawman. You cannot act as though feeding LLMs data is remotely comparable to reading.
minus-squareag_roberston_author ( ag_roberston_author@beehaw.org ) linkfedilinkEnglisharrow-up18·3 years agoBecause reading is an inherently human activity. An LLM consuming data from a training model is not.
minus-squareTheBurlapBandit ( TheBurlapBandit@beehaw.org ) linkfedilinkEnglisharrow-up7·3 years agoLLMs forcing us to take a look at ourselves and see if we’re really that special. I don’t think we are.
minus-squareDominic ( Dominic@beehaw.org ) linkfedilinkEnglisharrow-up6·3 years agoFor now, we’re special. LLMs are far more training data-intensive, hardware-intensive, and energy-intensive than a human brain. They’re still very much a brute-force method of getting computers to work with language.
minus-squaremonobot ( monobot@lemmy.ml ) linkfedilinkEnglisharrow-up0·3 years agoSo is suing, but thay managed to sue AI, so why not let it read too?
minus-squarepips ( Pips@lemmy.film ) linkfedilinkEnglisharrow-up5·3 years agoBecause the LLM is also outputting the copyrighted material.
minus-squareDouble_A ( Double_A@discuss.tchncs.de ) linkfedilinkEnglisharrow-up3·3 years agoSo could any human that got inspired by something…
This is a strawman.
You cannot act as though feeding LLMs data is remotely comparable to reading.
Why not?
Because reading is an inherently human activity.
An LLM consuming data from a training model is not.
LLMs forcing us to take a look at ourselves and see if we’re really that special.
I don’t think we are.
For now, we’re special.
LLMs are far more training data-intensive, hardware-intensive, and energy-intensive than a human brain. They’re still very much a brute-force method of getting computers to work with language.
So is suing, but thay managed to sue AI, so why not let it read too?
Because the LLM is also outputting the copyrighted material.
So could any human that got inspired by something…