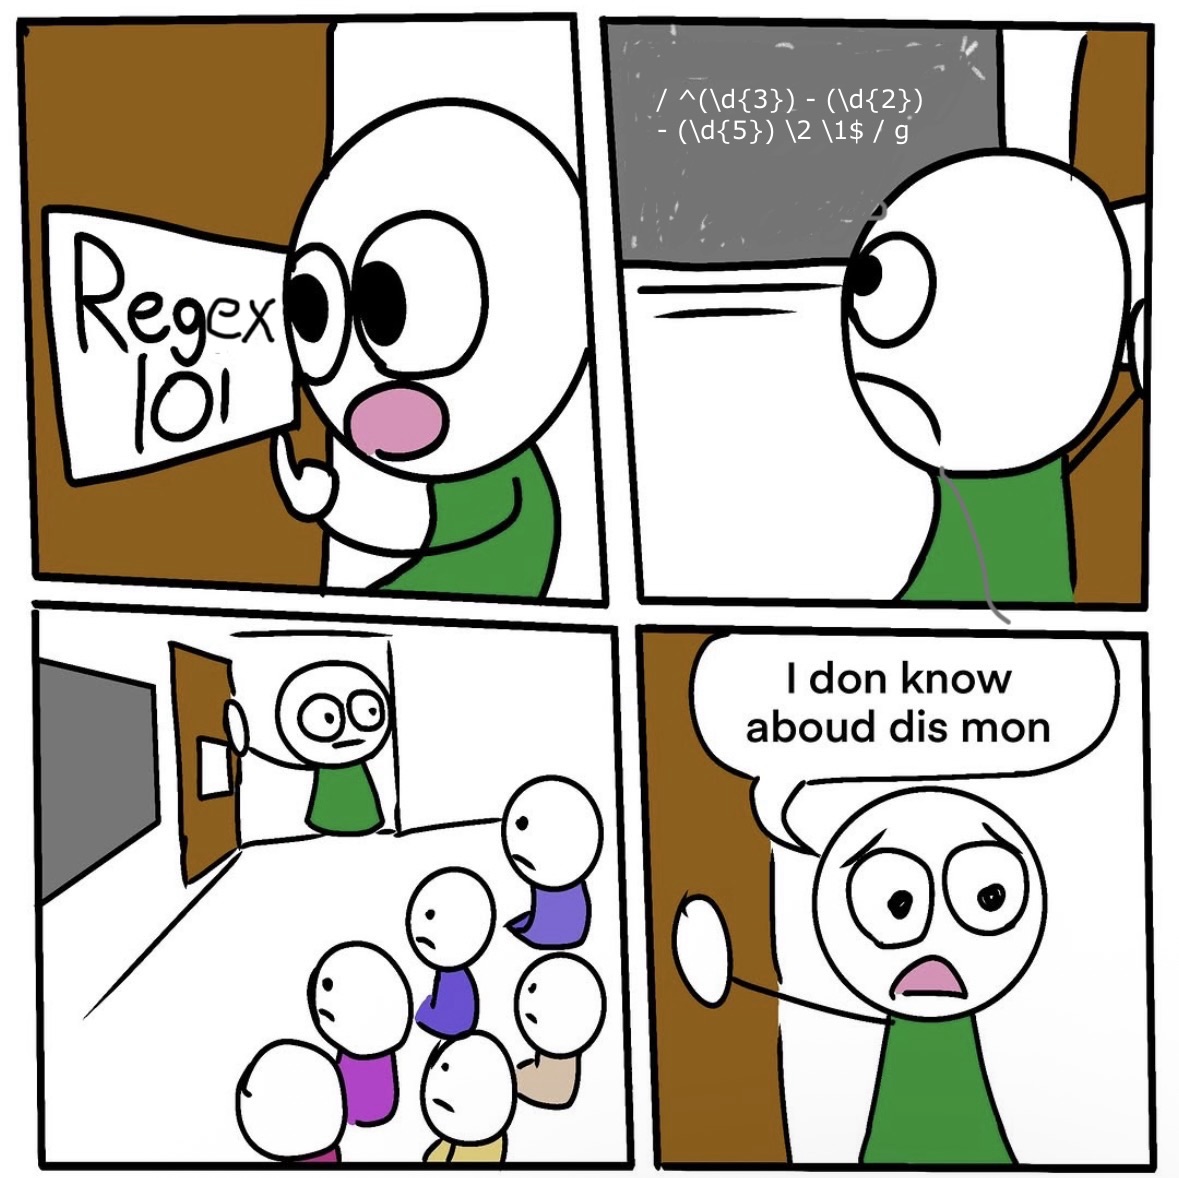
the original said reggae but i misread it as regex and got this idea lol
original comic artist: thisstupidtwink@insta
As someone who doesn’t know any regex syntax, is there any simple explanation for what the expression on the board does?
Basic concept: the purpose of regex is to search input text for matching patterns of characters.
Assuming this is correct (including the spaces):
/ ^(\d{3}) - (\d{2}) - (\d{5}) \2 \1$ / gThen:
/The first forward slash is the delimiter which tells the code that this is the start of the regex (start interpreting the expression after this).^The caret marks the beginning of the text string being searched for a match or the beginning of a line of text, meaning that any matches found by the following regex must begin at the beginning of the input text, or at the beginning of a new line of text, not somewhere in the middle of it.(\d{3})This is the first group for matching actual text characters. The\dmatches any single digit (0-9). The{3}attached to it means that there must be exactly 3 digits adjacent to each other, no more, no less._-_(underscore indicating that there is a space in the original expression) This must match a [space][dash][space] as literal characters.(\d{2})As before, this matches two adjacent digits. This is the second matching group._-_Same as above, [space][dash][space].(\d{5})Same as the two patterns before, this matches five adjacent digits. This is the third group._\2The [space] here matters, indicating that there must be a space character between the previously matched group of five digits and the following match group\2, which says to match the same text as the most recently matched 2nd group. In this case the second group would be(\d{2}), so this must match the same two digits as were matched by(\d{2})in the same order._\1Similar to the above, this must match a [space] and then the same text as the first most recently matched group. In this case that would be the(\d{3}).This is the same as the^, only it matches the end of the input text or the end of a line of text. This means that there cannot be any more characters in the input text after the last characters that match the specified pattern./ gThe/is again a delimiter, indicating the end of the regex. Thegmeans “global”, which instructs the code to search the entire input text for all possible matches and return all of them at the end of the search (default regex behavior is to search until the first match, then stop and return that result).So example matches would look like this:
111 - 22 - 33333 22 111
012 - 01 - 01234 01 012
987 - 98 - 98765 98 987But this would not match:
11 - 222 - 33333 222 11(incorrect numbers of digits in the first and second groups)
012 - 01 - 01234 10 012(the second group of 2 digits does not match the first group of 2 digits)
987-98-9876598987(spaces are missing)
111 22 33333 22 111(dashes are missing)
Speculation:
The matched string looks like a serial number or part number or something like that, so probably the use case for this regex is to search through a file containing a long list of such numbers all separated on new lines of text, to find specific ones (for some reason). Maybe numbers that match this pattern are invalid, or maybe only numbers that match this pattern are valid and everything else that might be in the file needs to be removed.Based on this I think the end is actually wrong and should be
/ gm(m for multi-line) to allow for searching (and returning) multiple lines of input text. Otherwise, this should be part of code which splits the lines of the input text file into individual strings and then feeds them through the regex one at a time - but if that’s the case then using theg(global) flag doesn’t really make sense.
With thanks to https://regex101.com/
Solid explanation
Updated because I clicked the reply button before it was actually done.
Oh lordy, that’s just a tad bit longer XD
Traditionally, the
globalflag is used to mean global within a line, meaning all matches in a line.Right, but this expression has an explicit
^and, so if there’s anything else in the input line besides a single instance of the pattern, it won’t match. This makes thegkind of pointless, there can’t possibly be multiple instances of the pattern in the same line and still return a valid match.
Never knew the repeat group bit. Can’t really think of a practical use case for it though…
I use it to parse HTML. Find a tag and the matching closing one (inside first)
Edit: last time it was a different-schema XML (not HTML) but whatever
I use it in Vim. Sometimes you want to rename a variable that’s present multiple times in the same line
Why not just match for the variable and use
/g?Why would you go the easy way when there is a complicated but infinitely cooler way?!
I assumed that’s what they meant by “group bit”. I guess maybe they were talking about capture groups
True, regex is nothing if not an everything tool!
(?:\d{3}-){2}(?:\d{4}) would match a ten digit us-format phone number, though I’d recommend using two literally instead of a repeat for maintainability reasons. Regex needs no assistance being terse and obtuse, humans need time to understand regex patterns, even ones they wrote not long ago. Make that part easier on your collaborators, and treat your past and future selves like remote asynchronous collaborators, always.
What you call delimiter is part of
sed, Ruby or Perl syntax, right? In Python, Regex strings are usually delimitedr" "(rfor raw: don’t process special characters)Usually regex by it self is shown with
/delimiter. Using it on code is language-specific. On rust you normally use"<regex>"#, on javascript you can just/<regex>/, but that’s just the language’s definition, not regex.In this context probably javascript, but yes the delimiter is more an artifact of the code language that the regex is being used in than it is part of the regex itself.
no
Fair enough lol
Curly braces are number of characters. Round braces are capture groups - their content can be used in search and replace. So abbba and regex a(b{3})a. Capture group 1 would be bbb.
“\” is usually some specific character. “\d” is any digit. “\s” is any whitespace character.
The thing on the board I don’t think is pure regex but a search and replace command and I think its wrong. It matches “272-43-17382” or similar digits. The 1 and 2 are usually capture groups in awk but on the board there is a “$” behind it which usually means end of string which doesn’t make sense. Should be I think:
“s/^(\d{3})-(\d{2})-(\d{5})$/\2 \1/g”
“Globally replace a string formatted like 273-34-27472 with 34 273”
!onehundredninetysix@lemmy.blahaj.zone
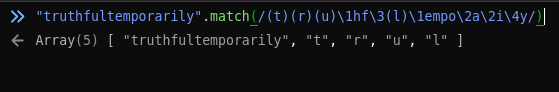
There’s something else: the backslash followed by a positive natural number means a reference to the nth capture group, so:"truthfultemporarily".match(/(t)(r)(u)\1hf\3(l)\1empo\2a\2i\4y/)…as esoteric as it may sound, will match your Lemmy username, because the
\1will correctly match the first capture group which ist,\2will match the second capture group which isr, and so on so forth… Oh, and it works beyond.replacecontexts, during.matchas well.Source: I just learned through this very meme and, from now on, I’ll likely use this feature whenever I have to use RegExp because I love coding cryptic one-liners just for the sake of it.
Heheh
I love bringing out all the nerds to talk on random niche topics :3
Right!? I love what you’ve caused here. Especially since I was wondering the same thing myself. I’m really enjoying these neat, informative replies! I <3 NERDS!
from the
/gat the end i agree it looks like it could be a malformed attempt at an awk/perl/etc substitution operation, and your rewrite of it as ans///does work, but the parts between the^andwould also be a valid regexp in Perl-compatible regexp and some other dialects if not for the spaces at the start and end. And, the/gis also a flag (“Match globally, i.e., find all occurrences.”) for them///matching operator in Perl.The
\1and\2are backreferences to the capture groups, which can be used not only in the replacement part but also in the pattern itself.You can see this working by running this command:
echo '123 - 45 - 67890 45 123'|perl -ne 'print if m/^(\d{3}) - (\d{2}) - (\d{5}) \2 \1$/g'…which will echo the string because it matches the pattern. (if you edit the input string to change, for instance, the last digit, it will no longer match and will output nothing.)
There is no input that can match the pattern as it is in the comic with the space before the
^and after thehowever.Interestingly backreferences are also supported by POSIX Basic Regular Expressions (BRE), but are not supported by POSIX Extended Regular Expressions (ERE). (Also the former requires you to escape parenthesis and curly braces for them to become meta characters, while the latter requires you to escape them if they’re literals as Perl etc do. And neither of the POSIX flavors supports
\das a shortcut for[].)This definitely seems like a possible use case, but personally I think practical application of sed would be a bit advanced for a “Regex 101” course.
Yeah, I think I’m catching the general idea.
A couple of years ago, there was a guy wanting to use some llm-based agentic whatever to extract a specific information from a group of research articles in pdf. His justification was that it was a complex kind of information that needed to be extracted. After the same task was assigned to me, I dumped the llm and did the same thing, with fewer errors and much faster, by just using some regex patterns with pdfgrep. It can be complicated, but it’s so powerful! And I don’t even know shit about regex, I just used a search engine and some trial and error lol
this inspired me to make another shitty meme here u go enjoy: https://lemmy.cafe/post/36565281
Expected the regex to match the sentence in the last frame…

!onehundredninetysix@lemmy.blahaj.zone TIL, through a meme (yep, memes can be very teaching, too), that I can reuse capture groups in a recurring manner inside a RegExp (I didn’t know about the
\(number)thing, but I readily inferred, due to past experience with using\(number)in KDE Kate’s Regexp replace, it had something to do with “this position must contain the nth group verbatim”, opened the DevTools, tried.matchwith a fixed version of the meme’s regex (i.e. without the invalid spaces) and a random phone sequence my mind conjured out of thin air, and voilá, the slash-number thing indeed behaved as I guessed it would behave). So… Thanks to whoever made the meme because TIL thanks to you!/^Be( )not\1(a)fr\2id$/(Biblically-accurate RegExp).This is a cool feature of a lot of regex implementations but I will warn you that reusing capture groups in a match means it’s impossible for any regex engine to guarantee a reasonable upper bound (best they can do is O(n!) I think? I’d have to look up the details). In a replacement string this is a non-issue because there’s no way they can recurse out of control.
Edit: found the video I originally heard this from: https://www.youtube.com/watch?v=gITmP0IWff0
yay you’re welcome!
Backreferences are bad for performance and make the grammar being matched irregular, if I remember my comp sci classes. I don’t they should be taught in a Regex 101 class.
maybe it says “Regex lol”
Are you thinking of lookarounds? Backreferences do have some performance impact but a lookahead or lookbehind much more so. That definitely breaks the regularity, but I’m not sure that applies to backreferences (which may be my own ignorance). Performance wise unmatched lookarounds are the least performant getting worse as the size of the corpus increases. A positive lookahead/lookbehind has to scan all the text before or after the assertion to determine match failure and likewise negatives must do the same to determine match success. Greedier matching also amplifies things here (do you want just the first match or all of them?)
I’m more fluent in regex syntaxes than in the implementation details of any specific regex engine, so please correct me if you know Im wrong, both for my own edification and so that when I share things going forward Im sharing the most accurate information that I can.
Turns out we’re both off the mark: it’s catastrophic backtracking that is “dangerously” vulnerable to performance issues. Something as simple as
(a+)+bis enough to trigger the “bad” behavior. I assume you can achieve it with back references and lookarounds as well.This video gives a good breakdown of what exactly is going on inside a compiled regex automata that encodes such a case: https://www.youtube.com/watch?v=gITmP0IWff0
Thank you friend! I honestly had almost forgotten that you could + on a group (in extended syntax i think?) like you can with *. In my experience I find lots of * groups and I do my best to convert those to a range eg {3,5}. When you can’t typically you can set least still use an open range floor {3,} or ceiling {,5}. I’m a big fan of explicit constraints when you have enough information to set them. It’s another good maintainability practice in my experience. The more clear the regex the less example data you need to understand the intention. I especially like eg ruby’s regexp.x flag that let’s you ignore literal newlines and whitespace in the pattern (not to be confused with regexp.X which does the same but for the corpus), so you can split your pattern over multiple lines. I like to use indentations when it helps readability and that also allows a multi line comment header indented the same way. Sometimes you can even set inline comments depending on language/engine/syntax. For significant whitespace in the pattern wrap each whitespace character in a character class containing only itself: eg [ ][ ] for two literal spaces to match. This is also how I handle patterns for eg sed or grep in bash/zsh which have their own whitespace semantics, to get whitespace literals in your patterns without the need to escape anything. The non-literal part of the pattern doesnt change, and the literal part gets substituted in piped through something like sed -E ‘/./[\1]/g’
And this is why I’m not a programmer
That’s not a problem at all. Most programmers don’t understand regex as well
you will find regex in numerous things that have nothing to do with writing code. i don’t even need to leave firefox to find several instances in the addons i have installed.
deleted by creator
deleted by creator